Flue
Flue's OpenTelemetry adapter, @flue/opentelemetry, traces every agent run, model turn, tool call and subagent task in GenAI semantic conventions, with the Flue conversation id on each span as gen_ai.conversation.id.
Oodle is a managed observability platform for metrics, logs, traces and agent traces. It ingests OpenTelemetry natively, so the snippet on this page is the complete setup.
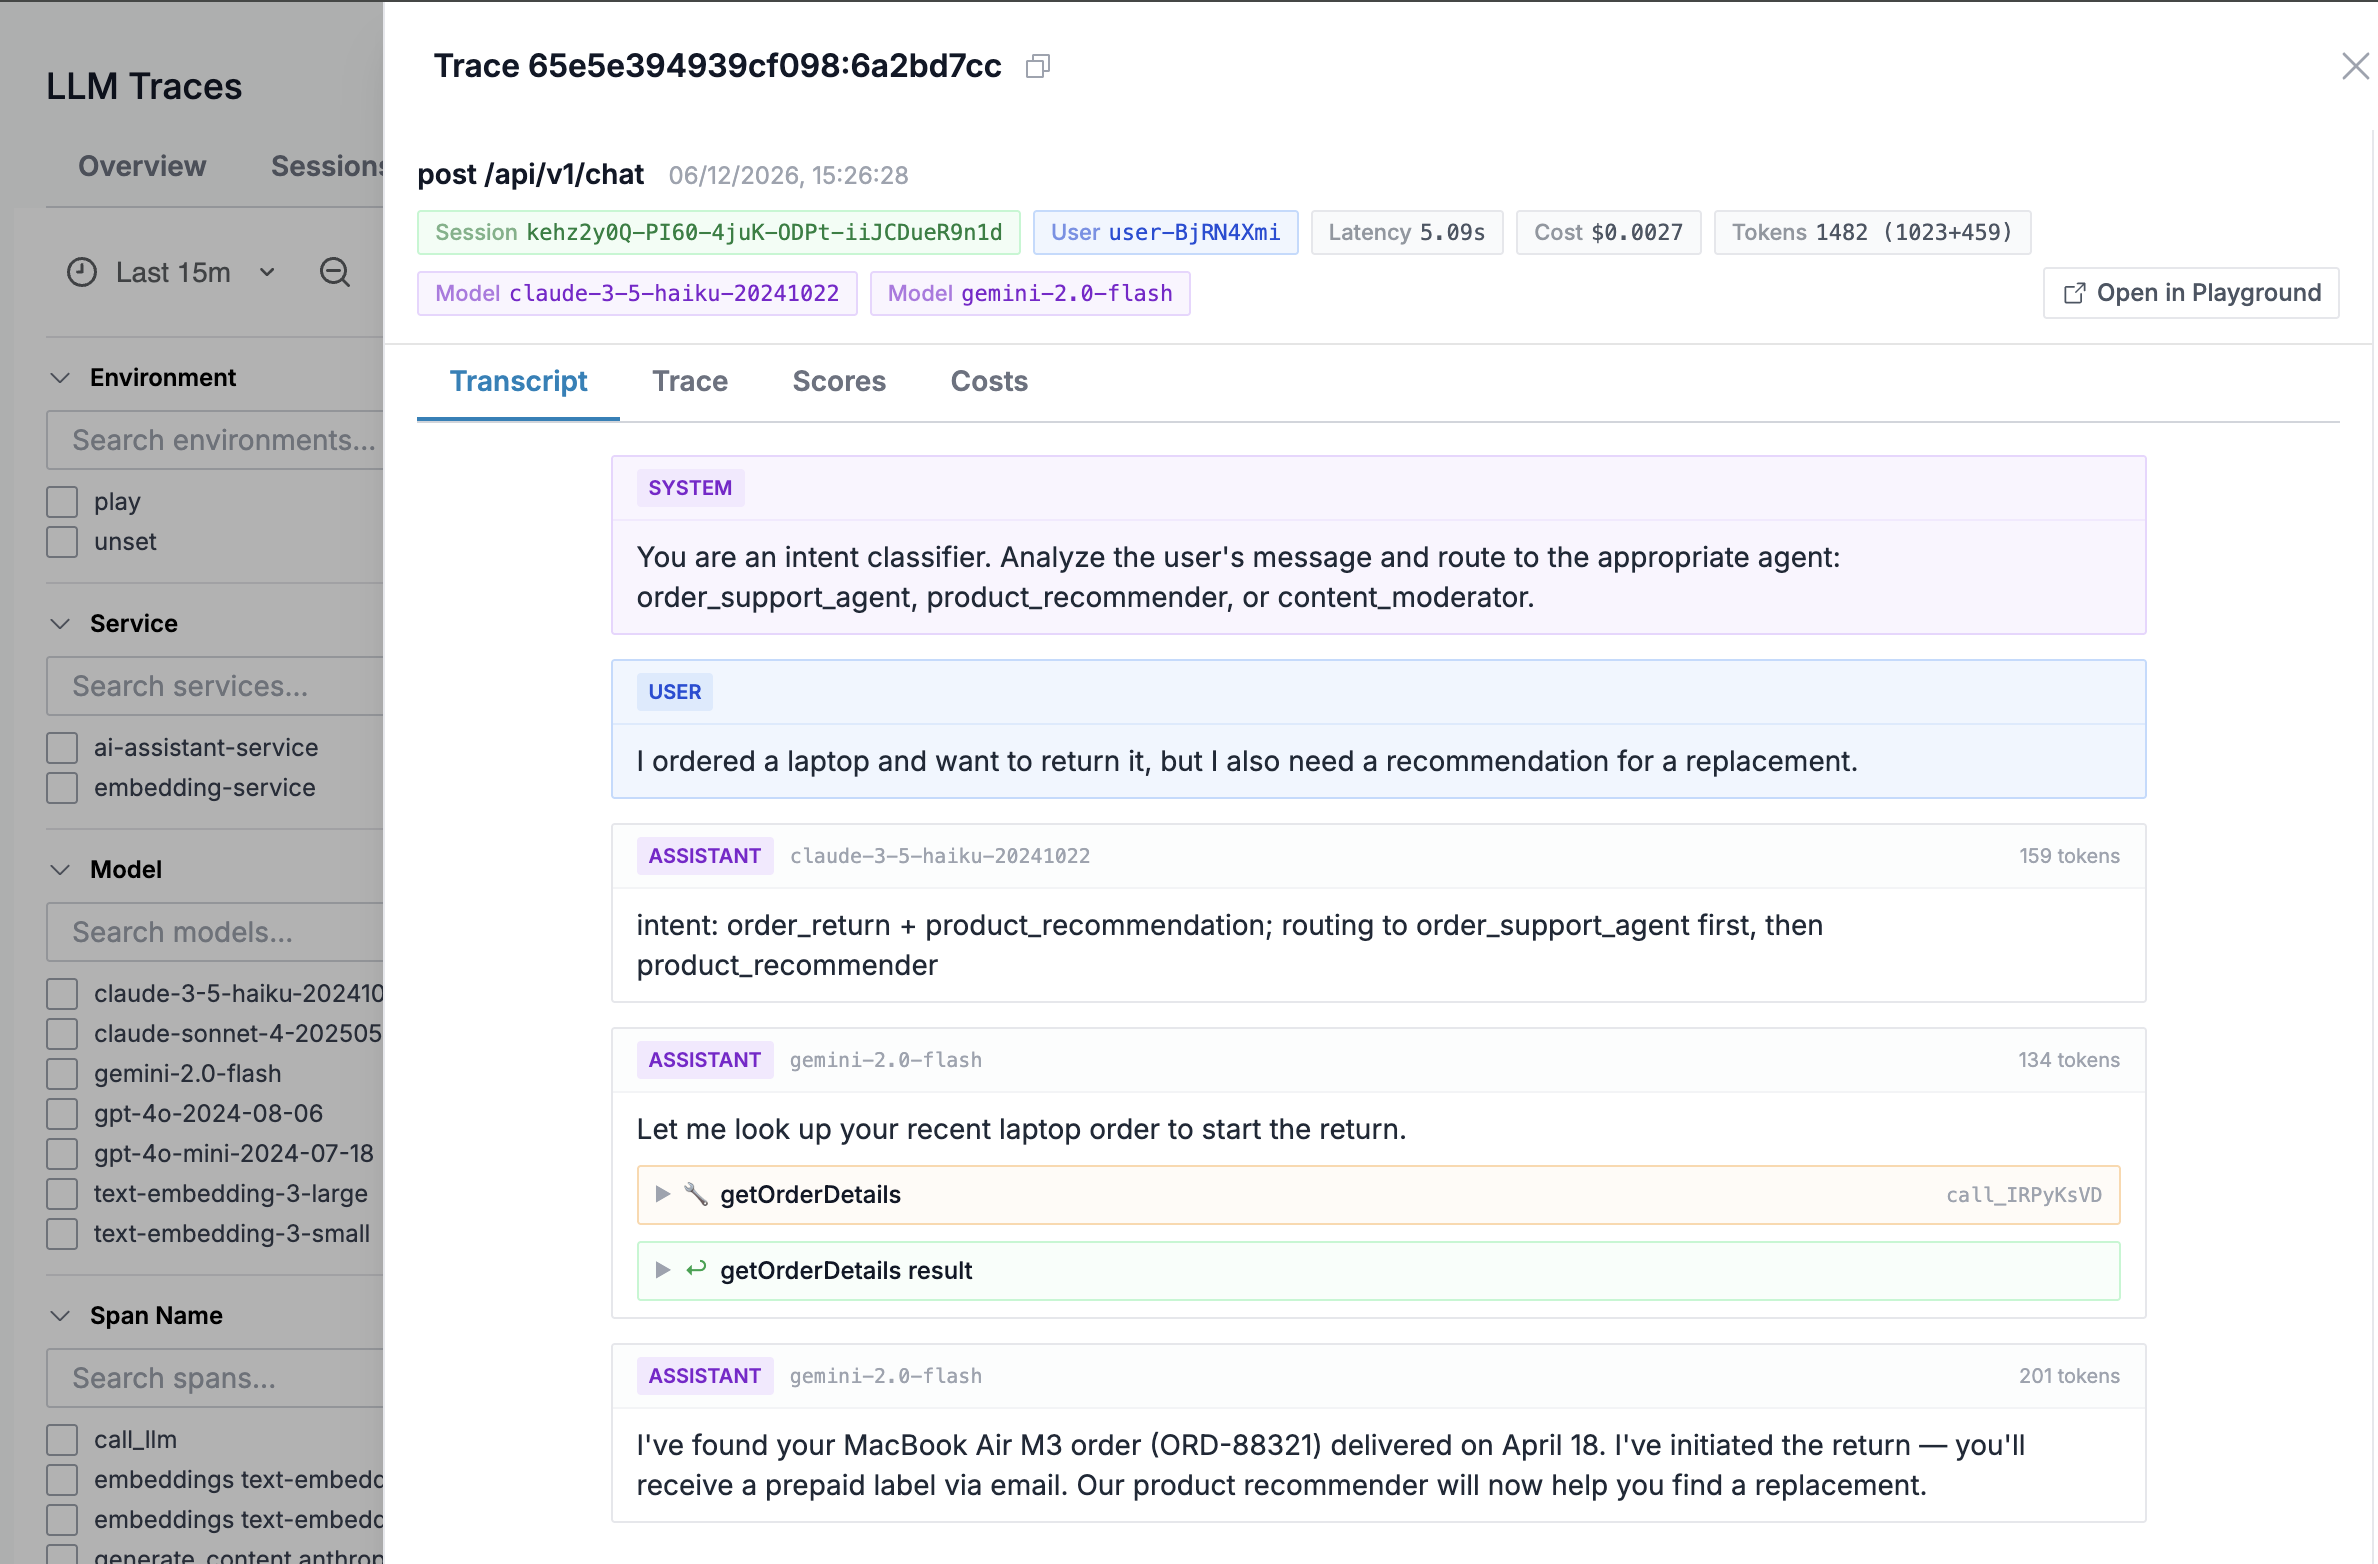
Each trace shows the full transcript, the token counts and cost of every call, the agent structure (runs, steps and tool calls) and Signals: labels for loops, rate limits, refusals and tool failures, detected as the trace arrives.
Sign up for free to get an instance ID and an API key, or see the Agent Observability overview first.
You will need:
OODLE_INSTANCE: your Oodle instance ID (ap1, us1)OODLE_API_KEY: an Oodle API key (ap1, us1)OTLP_ENDPOINT: your OTLP collector domain, shown on the tile
Open the Flue tile on the ap1, us1 page to
get these filled in for you, or let an agent do the setup with
/oodle-onboarding set up the llm_observability_flue integration.
Install
Install Flue's OpenTelemetry adapter with the OTel SDK. Keep the versions: the newest OTLP exporter and the Node tracer provider ask for different @opentelemetry/api versions, so npm cannot install them together unpinned:
npm install @flue/opentelemetry @opentelemetry/[email protected] \
  @opentelemetry/sdk-trace-node@2 @opentelemetry/resources@2 \
  @opentelemetry/[email protected]
Instrument
Configure the OTel SDK, then register Flue's instrumentation once, in a module app.ts imports first. Flue then traces every agent run, model turn, tool call and subagent task in GenAI semantic conventions, with the conversation id on each span:
// src/telemetry.ts
import { createOpenTelemetryInstrumentation } from '@flue/opentelemetry';
import { instrument, observe } from '@flue/runtime';
import { OTLPTraceExporter } from '@opentelemetry/exporter-trace-otlp-proto';
import { resourceFromAttributes } from '@opentelemetry/resources';
import { BatchSpanProcessor, NodeTracerProvider } from '@opentelemetry/sdk-trace-node';

// NodeTracerProvider does not read OTEL_SERVICE_NAME, so name
// the service here or every trace lands under
// unknown_service:node.
const provider = new NodeTracerProvider({
  resource: resourceFromAttributes({ 'service.name': 'my-llm-app' }),
  spanProcessors: [new BatchSpanProcessor(new OTLPTraceExporter())],
});

// Makes spans your own tools start join the agent trace.
provider.register();

// Prompts, replies, tool arguments and results are sent by
// default. Pass `content: false` to send spans without them.
instrument(
  createOpenTelemetryInstrumentation({
    tracer: provider.getTracer('@flue/opentelemetry'),
  }),
);

// The Flue server exits as soon as it stops, before a flush
// started on SIGTERM ends. Send each turn when it settles.
observe((event) => {
  if (event.type === 'submission_settled') void provider.forceFlush();
});

// src/app.ts - import the telemetry module first.
import './telemetry.ts';
import { createAgentRouter } from '@flue/runtime/routing';
import { Hono } from 'hono';
import { Assistant } from './agents/assistant.ts';

const app = new Hono();
app.route('/agents/assistant', createAgentRouter(Assistant));

export default app;
Environment
Point the application at Oodle:
# OTLP endpoint (points straight at Oodle)
export OTEL_EXPORTER_OTLP_ENDPOINT=https://<OTLP_ENDPOINT>

export OTEL_EXPORTER_OTLP_HEADERS="X-API-KEY=<OODLE_API_KEY>,X-OODLE-INSTANCE=<OODLE_INSTANCE>"

# Compress the export: prompt payloads are large
export OTEL_EXPORTER_OTLP_COMPRESSION=gzip
What each run becomes
| Flue activity | Span |
|---|---|
| A message to an agent, or a skill | invoke_agent <agent>, the root of the trace |
| A model turn | chat <model>, with the messages, system instructions, tool definitions and token counts |
| A tool call | execute_tool <tool>, with its arguments and result |
| A subagent task | invoke_agent <subagent>, under the agent that delegated it |
Each message is one trace. Every turn of one Flue conversation
carries the same gen_ai.conversation.id, so the Sessions view groups
them. That id is the one Flue makes (conv_...), not the id in the
agent URL: the URL id is on each span as flue.instance.id, so filter
on that attribute to find a conversation by your own id. Only the
chat spans carry token counts, so totals are not counted twice.
Under flue run
flue run loads only the agent module and never app.ts, so a
telemetry module that app.ts imports does not run there. To trace
flue run, import the telemetry module from the agent module as well.
vite dev and the built server load app.ts.
Restarts
The Flue server exits as soon as it stops, so the snippet sends each
turn when its submission settles rather than on SIGTERM. A turn that
a restart interrupts sends no spans: they never end. With a
database, Flue resumes
that work on the next start.
Content
The adapter sends prompts, replies, system instructions, tool
arguments and results, and exception messages by default. Pass
content: false to createOpenTelemetryInstrumentation() to send
spans without them, or content: { transform } to redact them in code.
Verify
Run your application, then open ap1, us1. Spans
carry gen_ai.* attributes: the model, token counts, and the prompt and
response content. Click a trace for the Transcript, the waterfall, and
the cost breakdown.
If nothing arrives, check that the exporter can reach
https://<OTLP_ENDPOINT> and that the instance and key are set: the
OTLP gateway answers 401 without them.
Support
If you need assistance or have any questions, please reach out to us through:
- Email at [email protected]