LangGraph
LangGraph runs every node through the LangChain callback system, so the LangChain instrumentation traces the graph run, each node, every model call and every tool call.
Oodle is a managed observability platform for metrics, logs, traces and agent traces. It ingests OpenTelemetry natively, so the snippet on this page is the complete setup.
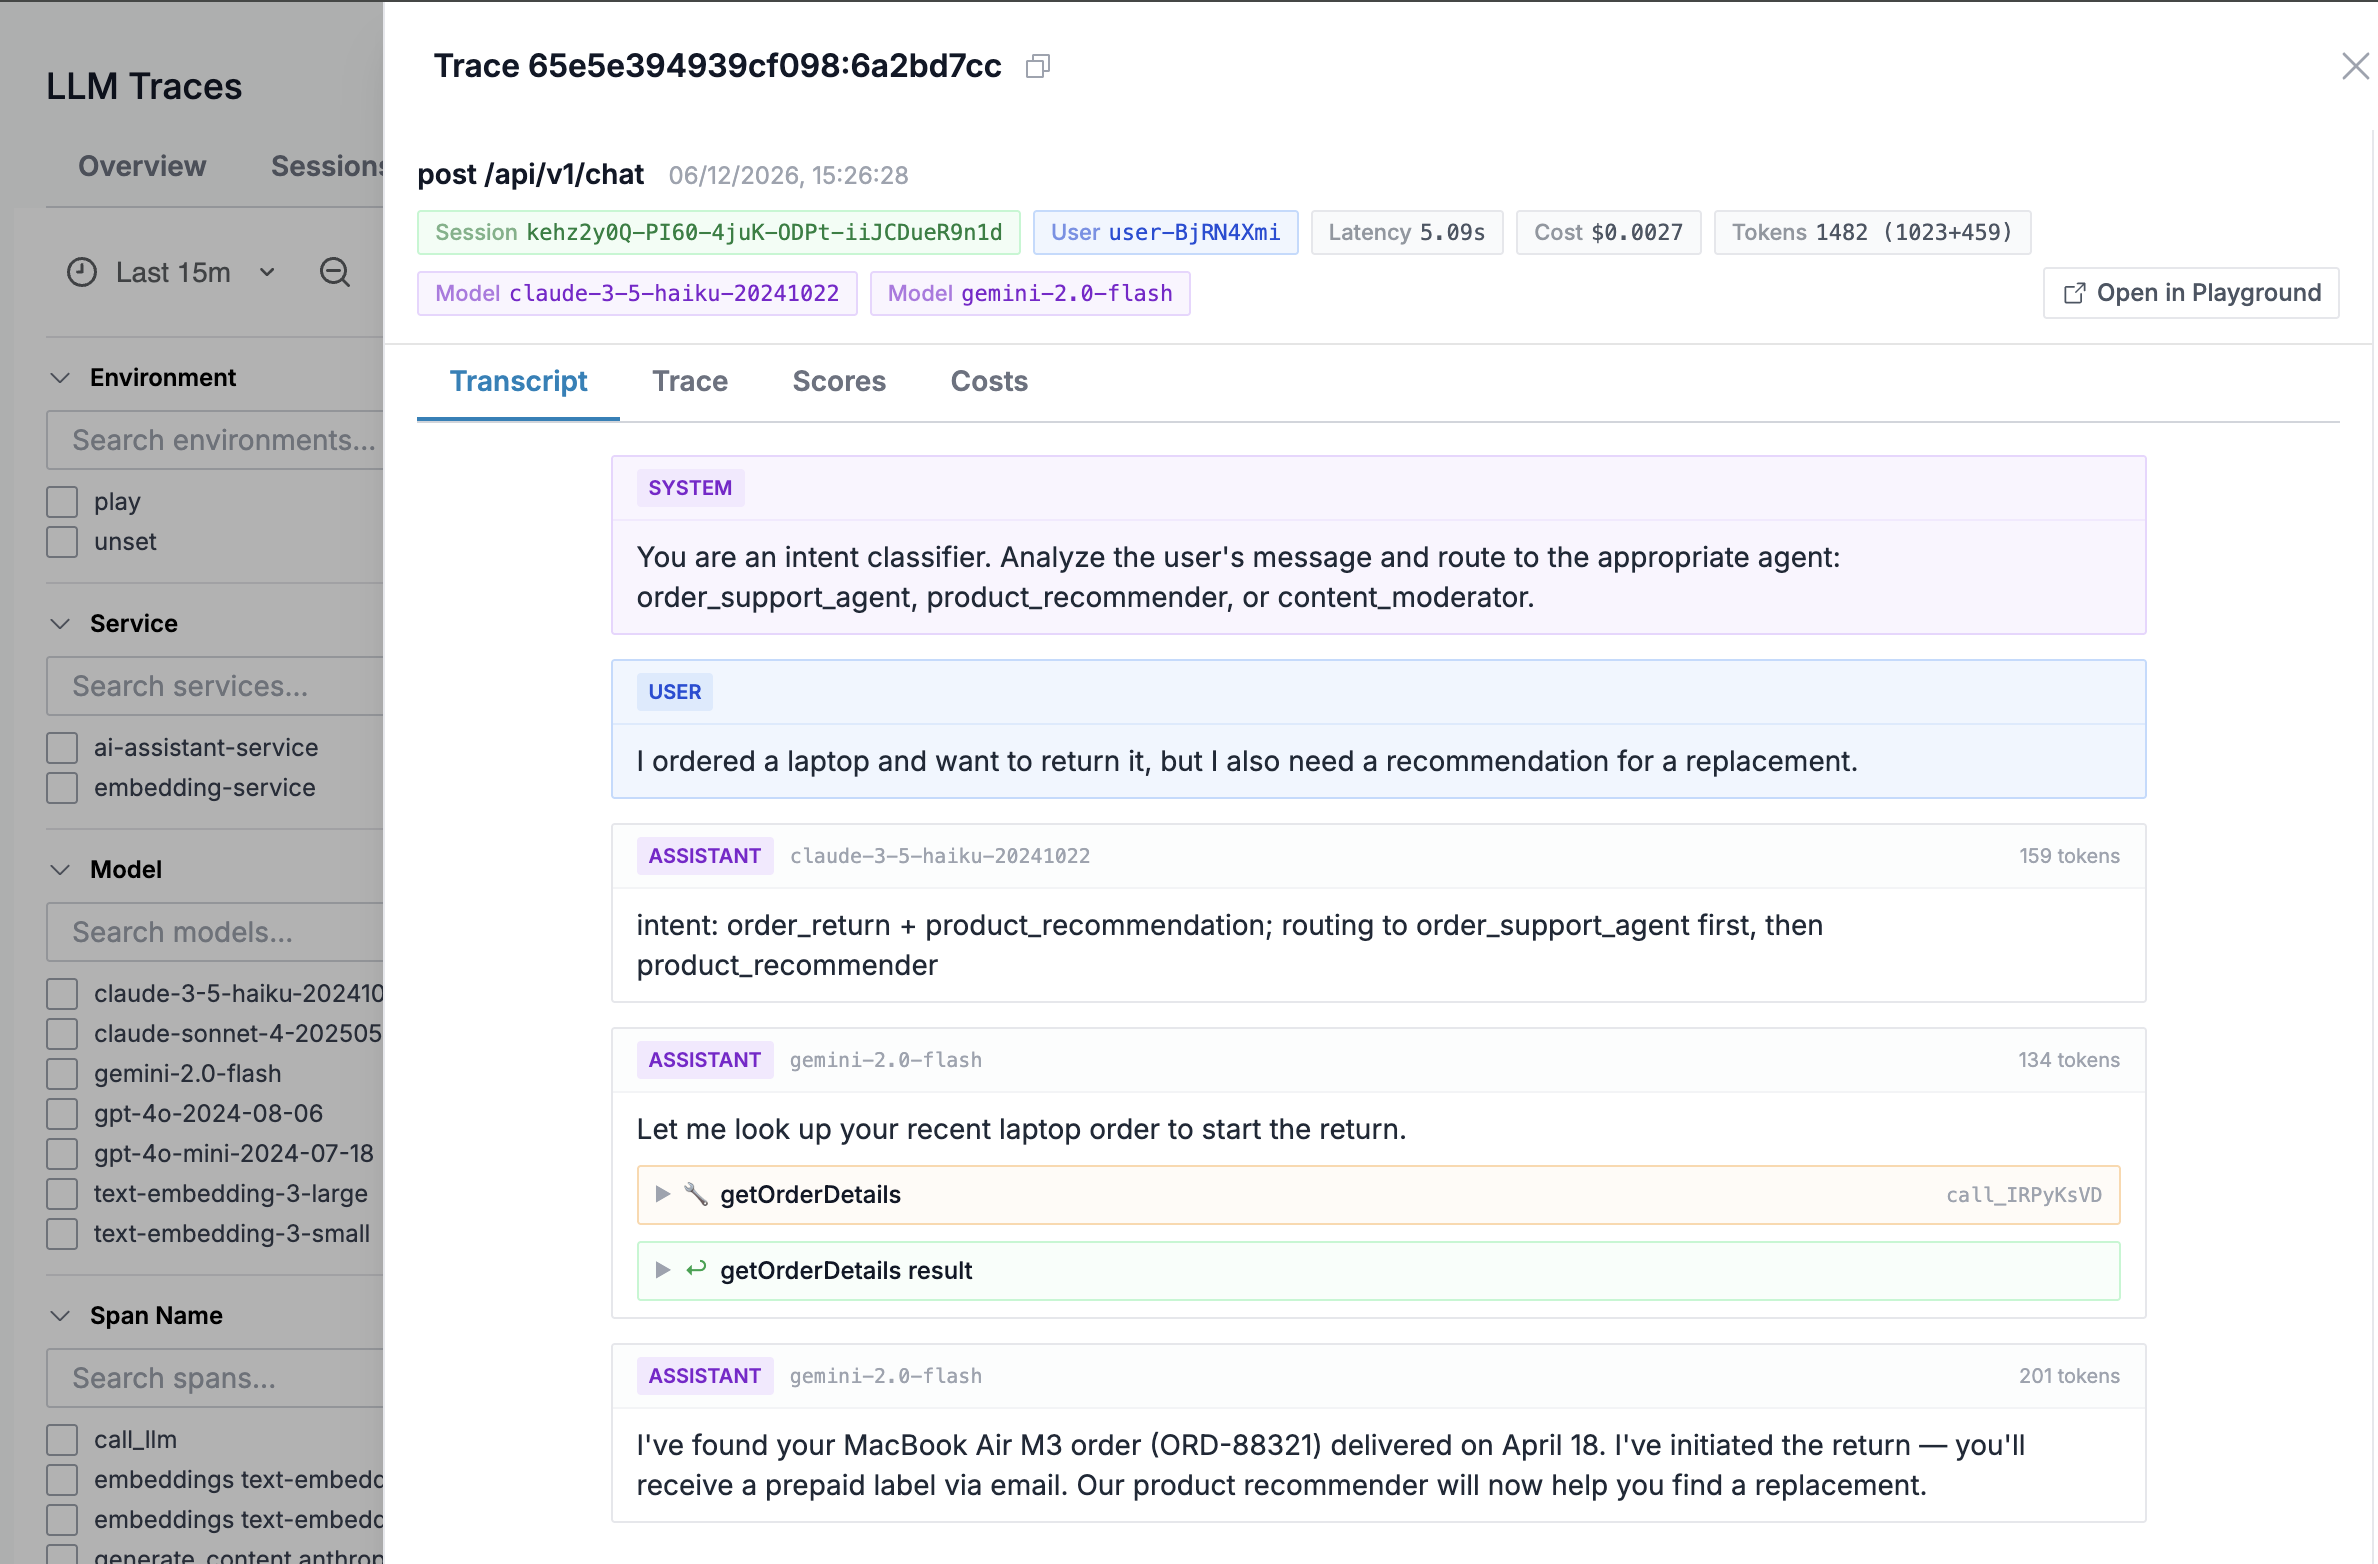
Each trace shows the full transcript, the token counts and cost of every call, the agent structure (runs, steps and tool calls) and Signals: labels for loops, rate limits, refusals and tool failures, detected as the trace arrives.
Sign up for free to get an instance ID and an API key, or see the Agent Observability overview first.
You will need:
OODLE_INSTANCE: your Oodle instance ID (ap1, us1)OODLE_API_KEY: an Oodle API key (ap1, us1)OTLP_ENDPOINT: your OTLP collector domain, shown on the tile
Open the LangGraph tile on the ap1, us1 page to
get these filled in for you, or let an agent do the setup with
/oodle-onboarding set up the llm_observability_langgraph integration.
Python
Install
Install LangGraph with the LangChain OTel instrumentor:
pip install langgraph langchain-openai \
  opentelemetry-instrumentation-langchain \
  opentelemetry-exporter-otlp-proto-http \
  opentelemetry-sdk
Instrument
Initialize OpenTelemetry and activate the LangChain instrumentor. LangGraph runs every node through the LangChain callback system, so the graph, each node, every model call and every tool call is traced:
from langchain_core.messages import HumanMessage
from langchain_core.tools import tool
from langchain_openai import ChatOpenAI
from langgraph.graph import START, MessagesState, StateGraph
from langgraph.prebuilt import ToolNode, tools_condition
from opentelemetry.exporter.otlp.proto.http.trace_exporter import OTLPSpanExporter
from opentelemetry.instrumentation.langchain import LangchainInstrumentor
from opentelemetry.sdk.resources import Resource
from opentelemetry.sdk.trace import TracerProvider
from opentelemetry.sdk.trace.export import BatchSpanProcessor
from opentelemetry.trace import set_tracer_provider


def setup_opentelemetry():
    resource = Resource.create({"service.name": "my-llm-app"})

    tracer_provider = TracerProvider(resource=resource)
    tracer_provider.add_span_processor(
        BatchSpanProcessor(OTLPSpanExporter())
    )
    set_tracer_provider(tracer_provider)


setup_opentelemetry()

# LangGraph runs its nodes through the LangChain callback
# system, so this traces the graph, each node, every model
# call and every tool call. No manual spans required.
LangchainInstrumentor().instrument()


@tool
def get_weather(city: str) -> str:
    """Return the weather for a city."""
    return f"Sunny in {city}"


llm = ChatOpenAI(model="gpt-4o-mini").bind_tools([get_weather])


def call_model(state: MessagesState):
    return {"messages": [llm.invoke(state["messages"])]}


# A ReAct loop: model -> tools while the model asks for them.
graph = StateGraph(MessagesState)
graph.add_node("model", call_model)
graph.add_node("tools", ToolNode([get_weather]))
graph.add_edge(START, "model")
graph.add_conditional_edges("model", tools_condition)
graph.add_edge("tools", "model")
agent = graph.compile()

result = agent.invoke(
    {"messages": [HumanMessage("What is the weather in Paris?")]}
)
print(result["messages"][-1].content)
Environment
Point the application at Oodle:
# OTLP endpoint (points straight at Oodle)
export OTEL_EXPORTER_OTLP_ENDPOINT=https://<OTLP_ENDPOINT>

export OTEL_EXPORTER_OTLP_HEADERS="X-API-KEY=<OODLE_API_KEY>,X-OODLE-INSTANCE=<OODLE_INSTANCE>"

# Compress the export: prompt payloads are large
export OTEL_EXPORTER_OTLP_COMPRESSION=gzip

# Optional: disable prompt/response capture
# export TRACELOOP_TRACE_CONTENT=false
TypeScript / JavaScript
Install
Install LangGraph with the LangChain OTel instrumentor:
npm install @traceloop/instrumentation-langchain \
  @opentelemetry/api \
  @opentelemetry/instrumentation \
  @opentelemetry/exporter-trace-otlp-proto \
  @opentelemetry/resources \
  @opentelemetry/sdk-trace-base \
  @opentelemetry/sdk-trace-node \
  @opentelemetry/semantic-conventions \
  @langchain/langgraph @langchain/openai @langchain/core zod
Instrument
Initialize OpenTelemetry and activate the LangChain instrumentor. LangGraph runs every node through the LangChain callback system, so the graph, each node, every model call and every tool call is traced:
// instrumentation.js
const { LangChainInstrumentation } = require('@traceloop/instrumentation-langchain');
const { registerInstrumentations } = require('@opentelemetry/instrumentation');
const { OTLPTraceExporter } = require('@opentelemetry/exporter-trace-otlp-proto');
const { resourceFromAttributes } = require('@opentelemetry/resources');
const { BatchSpanProcessor } = require('@opentelemetry/sdk-trace-base');
const { NodeTracerProvider } = require('@opentelemetry/sdk-trace-node');
const { ATTR_SERVICE_NAME } = require('@opentelemetry/semantic-conventions');

const provider = new NodeTracerProvider({
  resource: resourceFromAttributes({ [ATTR_SERVICE_NAME]: 'my-llm-app' }),
  spanProcessors: [new BatchSpanProcessor(new OTLPTraceExporter())],
});
provider.register();

// LangGraph runs its nodes through the LangChain callback
// manager, so this traces each node, every model call and
// every tool call.
registerInstrumentations({ instrumentations: [new LangChainInstrumentation()] });

process.on('beforeExit', () => provider.shutdown());

// app.js
const { trace } = require('@opentelemetry/api');
const { HumanMessage } = require('@langchain/core/messages');
const { tool } = require('@langchain/core/tools');
const { StateGraph, MessagesAnnotation, START } = require('@langchain/langgraph');
const { ToolNode, toolsCondition } = require('@langchain/langgraph/prebuilt');
const { ChatOpenAI } = require('@langchain/openai');
const { z } = require('zod');

const tracer = trace.getTracer('my-llm-app');

const getWeather = tool(async ({ city }) => `Sunny in ${city}`, {
  name: 'get_weather',
  description: 'Return the weather for a city.',
  schema: z.object({ city: z.string() }),
});

const llm = new ChatOpenAI({ model: 'gpt-4o-mini' }).bindTools([getWeather]);

// A ReAct loop: model -> tools while the model asks for them.
const agent = new StateGraph(MessagesAnnotation)
  .addNode('model', async (state) => ({
    messages: [await llm.invoke(state.messages)],
  }))
  .addNode('tools', new ToolNode([getWeather]))
  .addEdge(START, 'model')
  .addConditionalEdges('model', toolsCondition)
  .addEdge('tools', 'model')
  .compile();

async function main() {
  // The LangChain spans join the span that is active when they
  // start. Open one per run so the nodes, model calls and tool
  // calls arrive as one trace; under an instrumented HTTP server
  // the request span already does this.
  const result = await tracer.startActiveSpan(
    'invoke_agent weather-agent',
    {
      attributes: {
        'gen_ai.operation.name': 'invoke_agent',
        'gen_ai.agent.name': 'weather-agent',
      },
    },
    async (span) => {
      try {
        return await agent.invoke({
          messages: [new HumanMessage('What is the weather in Paris?')],
        });
      } finally {
        span.end();
      }
    }
  );
  console.log(result.messages.at(-1).content);
}

main();
Environment
Point the application at Oodle:
# OTLP endpoint (points straight at Oodle)
export OTEL_EXPORTER_OTLP_ENDPOINT=https://<OTLP_ENDPOINT>

export OTEL_EXPORTER_OTLP_HEADERS="X-API-KEY=<OODLE_API_KEY>,X-OODLE-INSTANCE=<OODLE_INSTANCE>"

# Compress the export: prompt payloads are large
export OTEL_EXPORTER_OTLP_COMPRESSION=gzip

# Load the instrumentation before your app, so LangChain is
# patched as it loads.
node --require ./instrumentation.js app.js
Verify
Run your application, then open ap1, us1. Spans
carry gen_ai.* attributes: the model, token counts, and the prompt and
response content. Click a trace for the Transcript, the waterfall, and
the cost breakdown.
If nothing arrives, check that the exporter can reach
https://<OTLP_ENDPOINT> and that the instance and key are set: the
OTLP gateway answers 401 without them.
Support
If you need assistance or have any questions, please reach out to us through:
- Email at [email protected]